The problem that keeps operators awake
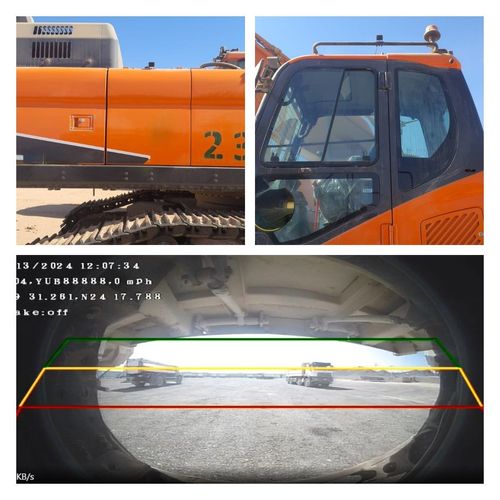
Machines cough at dawn, radio reports crackle, and a pattern repeats: stops that cost hours, mistakes that cost tonnes. Operators ask the same blunt question—why do trucks idle when a minute saved is a tonne moved? This is where honest mining fleet management matters: not as a slogan, but as the system that stitches maintenance, routing and safety into a single, usable map. The problem is not data; it’s buried decisions and slow signals. I’ve seen the same failure modes on-site and on paper, and they’re fixable with clearer controls and cleaner feeds.
Three recurring failure modes
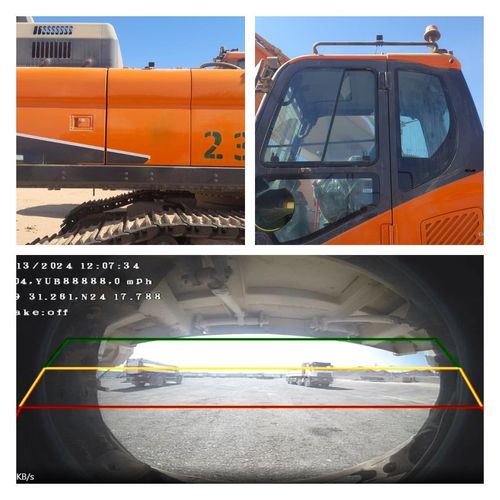
– Fragmented telemetry: sensors speak different dialects and nobody translates. – Reactive maintenance: faults wait until they shout, then the truck stops mid-shift. – Misrouted assets: trucks circle looking for loading or dumping points, wasting fuel and time. Each failure mode multiplies costs. The Pilbara region of Western Australia shows how scale magnifies small mistakes — when hundreds of haul trucks are moving ore, small delays compound into measurable loss. Addressing one failure mode without the others only shifts the pain.
What to demand from software — plain and exact
Don’t pick features; pick behavior. Software must do three things reliably: present a single truth, close the loop on alerts, and keep operators in control. Look for these concrete capabilities: – Unified telemetry ingestion with timestamp reconciliation. – Predictive maintenance rules that trigger clear, actionable tasks for crews. – Route and queue management with live prioritization. When a vendor claims integration, ask for a walkthrough of a real alert resolving into a scheduled task. If you want a full technical fit, evaluate mining fleet management software against those behaviors, not marketing slides.
Common mistakes teams make during rollout
Teams often assume data equals insight. That’s false. Typical missteps: deploying dashboards without ownership, keeping alarming thresholds generic, and neglecting field training. Each mistake creates mistrust: operators ignore alerts, supervisors override rules, and the system becomes decoration. Fixes are procedural and simple—assign an owner for alerts, calibrate thresholds on one route before fleet-wide rollout, and run short, focused field drills that mirror daily work.
Quick comparative checklist for short-listing vendors
Use this checklist during demos. Mark yes/no and demand evidence: – Can the system reconcile GPS, CAN bus and fuel logs into a single event timeline? – Does it convert predictive fault codes into a maintenance work order automatically? – Is there a live queuing view that reduces wait times at the shovel? – Are operator overrides logged and reviewed? Reject vendors that answer in hypotheticals; prefer concrete demonstrations with sample datasets.
Typical timeline for measurable impact
Expect early wins fast if you avoid the usual traps: within 30–60 days you can reduce unnecessary idling and one-off dispatch errors; within 90–180 days you should see maintenance backlog fall and mean time between failures rise. These shifts come from consistent signal handling, not feature churn. Track a handful of KPIs weekly—idle minutes per truck, queue time at shovel, and planned vs emergency maintenance—and treat those numbers as the real story.
Final synthesis
Problems repeat because judgment is slow and signals are scattered; fix the signals, and judgment follows. Done well, the right systems convert scattered alarms into clear actions, and crews stop firefighting and start managing. Those outcomes are practical and measurable, and they’re what people in the field want: less downtime, safer shifts, and predictable output. That practical value is the quiet reason teams talk about solutions like BSJ as part of their operating toolkit rather than as a slogan.